Experiment Tracking
Log, compare, and reproduce your machine learning experiments with ease.
Evaluate AI
Accelerate your AI development with powerful tools for training, experimentation, and deployment.
 Altindex
 Arkia
 Hearns
 Humblytics
 Nomura
 Osaic
 Spikes
 Woho
 AFI
 AWS
 GBT
 OpenAI
WHAT WE OFFER
Our platform is designed to streamline the entire machine learning lifecycle for developers, from rapid prototyping to scalable deployment.
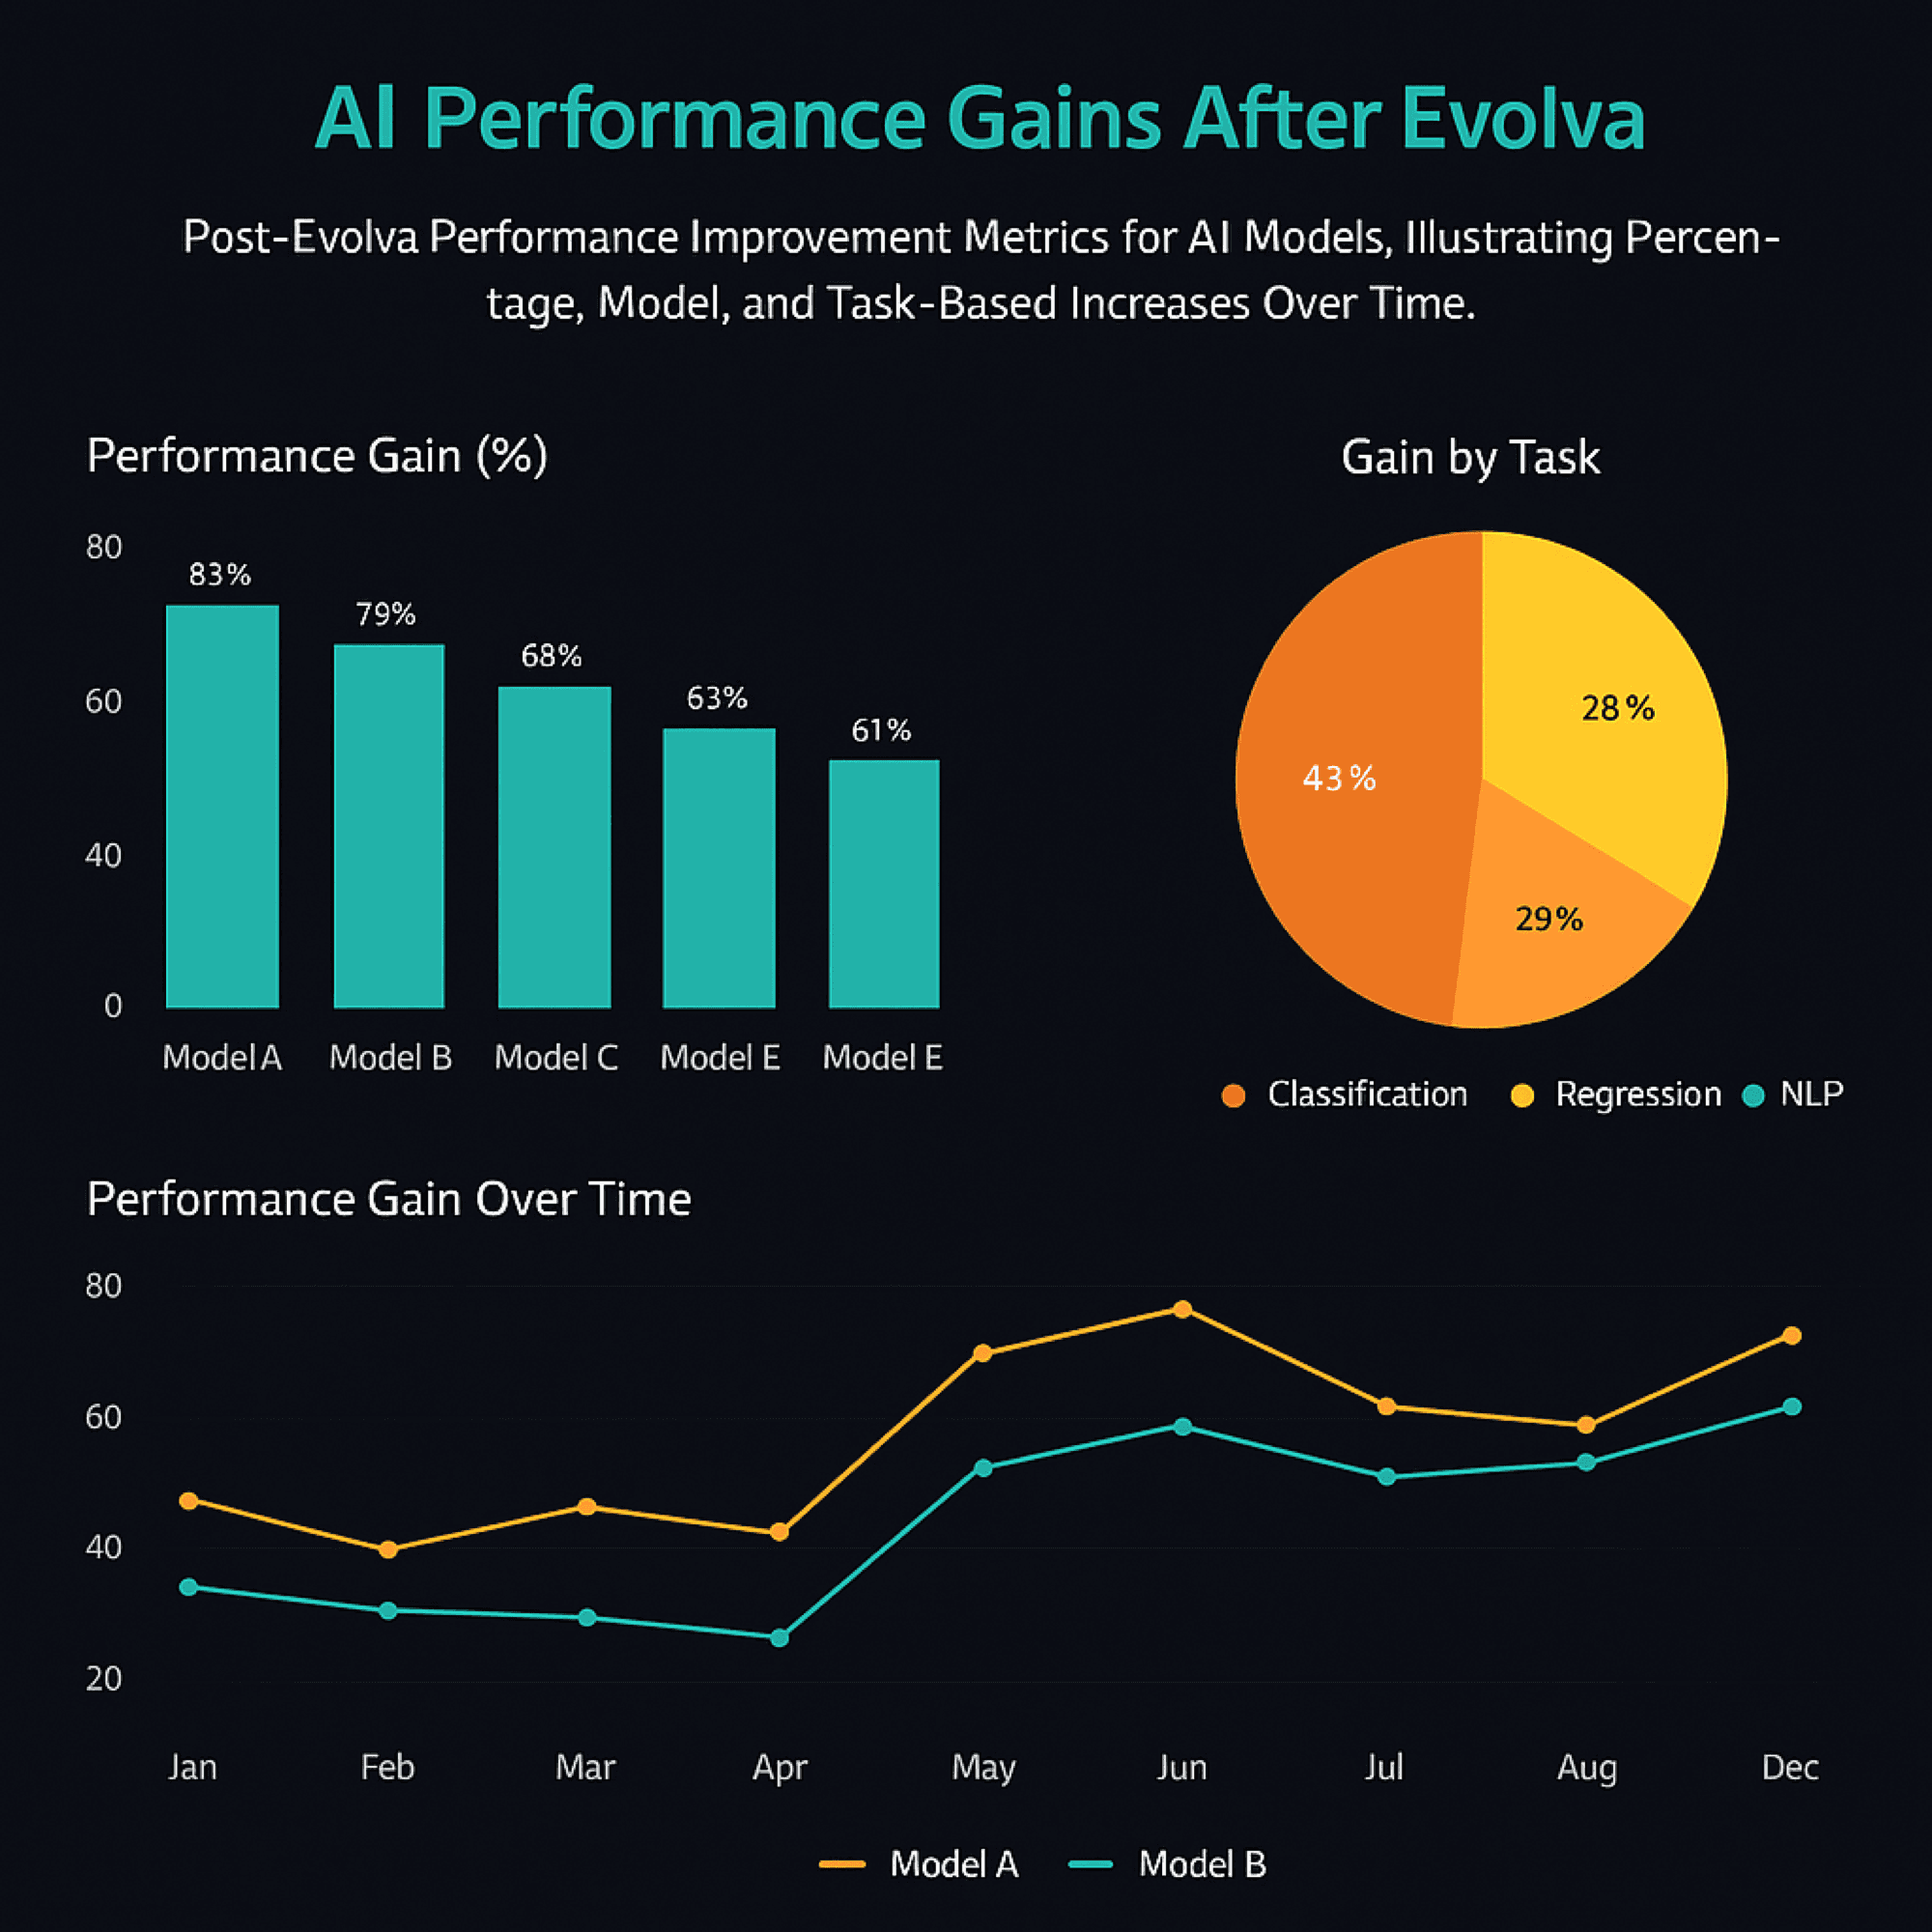
Empower your team to build, deploy, and manage AI models more efficiently and effectively.
Streamline your workflow to experiment and deploy models at an accelerated pace.
Leverage advanced tools for better model understanding and optimization.
Automate repetitive tasks and simplify infrastructure management.
Work seamlessly with your team on shared projects and model repositories.
EVALUATION CHALLENGES
WHY CHOOSE EVOLVA
Evolva’s Evaluation Suite empowers leading AI teams to understand, measure, and improve large language models (LLMs) with precision and confidence. Built for frontier AI, it offers deep visibility into performance and safety—across every dimension.
Access expertly curated datasets spanning domains and capabilities—engineered to prevent overfitting and provide accurate, unbiased assessments.
Skilled human reviewers deliver consistent, transparent feedback—reinforced by rigorous quality controls and performance benchmarks.
A seamless UI designed for clear analysis, side-by-side comparisons, and tracking model performance across iterations, domains, and capabilities.
Deploy custom evaluations to address specific performance gaps—then use the insights to drive model improvement with new training data.
Enable apples-to-apples comparisons across models with a reliable framework for fair, repeatable, and transparent evaluation.
Identifying and Mitigating Critical AI Vulnerabilities
Transforming Evaluation from a Bottleneck into a Breakthrough
Problem:Scarcity of unbiased, representative evaluation datasets
Evolva’s Solution:We design proprietary, high-quality evaluation sets that reflect real-world complexity across diverse domains—preventing overfitting and surfacing true model behavior.
Problem:Poor product experience for understanding results
Evolva’s Solution:Our platform provides rich visualizations, performance tracking over time, slice-and-dice analytics, and customizable test creation—giving ML teams full visibility and control.
Problem:Inconsistent evaluation and reporting practices
Evolva’s Solution:We offer a unified evaluation framework with consistent metrics, test conditions, and documentation—enabling fair comparisons between versions and competitors.
Problem:Undetected risks like bias, misinformation, and harmful outputs
Evolva’s Solution:From red-teaming and bias auditing to PII detection and ethical risk classification, Evolva identifies vulnerabilities early—so you can remediate before deployment.
Problem:Inadequate human involvement or quality control
Evolva’s Solution:Tap into a network of vetted linguists, analysts, and domain specialists, combined with rigorous QA pipelines, to ensure every evaluation is accurate, trusted, and actionable.
GET STARTED
Connect with our experts to discover how Evolva's AI solutions can revolutionize your data strategy and drive unparalleled growth.